Count Your Events Before You Count Your Variables
Published:
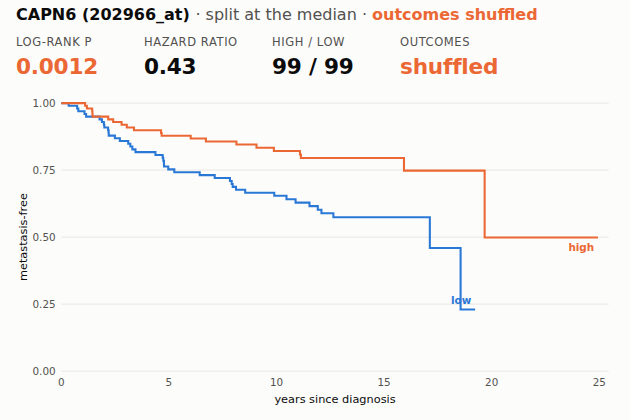
A model does not learn from your samples. It learns from your events. If your rare outcome occurred forty times and you are considering twenty thousand genes, you are asking forty facts to adjudicate twenty thousand questions, and most of what comes back is the sound of the data overfitting.
There is a number that governs whether a predictive model can mean anything, and it is not the sample size everyone quotes. It is the number of outcome events per candidate predictor, EPV. In a binary outcome it is the count of the rarer class divided by the number of predictors you let the model consider. In survival it is the number of events rather than the number of patients. This number is the real currency, and in omics we are almost always broke, while reporting our wealth in the wrong denomination.
Where the rule comes from
Peduzzi and colleagues ran the simulation that gave the field its rule of thumb. With ten or more events per variable, no major problems occurred. Below ten, logistic regression coefficients were biased in both directions, the model’s variance estimates both over- and understated the true sampling variance, confidence intervals lost their coverage, and paradoxical associations, significant in the wrong direction, became more frequent. The threshold isn’t sacred. Harrell’s course notes now put the rule at fifteen events per candidate parameter for a model whose apparent discrimination will hold up on validation, and Riley and colleagues have since replaced the rule of thumb with a calculation (more on that below). But the shape of the finding is robust. Below a certain events-per-predictor budget, the model is fitting noise, and it cannot tell you it is doing so, because the apparent fit on the training data looks better the more it overfits.
Notice what counts as a predictor. It is not the number of variables in your final model. It is the number you considered: every gene you screened, every threshold you searched, every interaction you tested. The degrees of freedom you spend looking count against you even when the search discards them. This is why “I only kept twenty genes” is not a defense if you chose those twenty from twenty thousand. You spent the whole budget on the search, and the twenty survivors carry all the optimism of having won a large competition on limited evidence.
The omics arithmetic is brutal
Put real numbers to it. A respectable clinical-omics study might have 300 patients and 60 events. Peduzzi’s rule says that supports honestly estimating on the order of six predictors. Six, not six thousand. Against that budget we routinely field expression matrices with twenty thousand genes, and then act surprised when the resulting signature doesn’t replicate (it can’t) or the accuracy estimate collapses on new data (it was never real). The gap between what the data can support and what we ask of them is a factor of thousands.
This is the same wall the last two posts ran into from different directions. Signature instability is what an EPV violation looks like when you inspect which features get chosen. Miscalibration and optimism are what it looks like when you inspect how well the model appears to do. They are one problem: too little evidence spread across too many parameters, letting noise masquerade as structure.
You cannot cross-validate your way out
The most common misconception is that cross-validation fixes this. It does not fix the EPV problem; it only measures it, and only if you do it honestly, with the entire modeling pipeline, including feature selection, rerun inside every fold. If you select features on the full dataset and then cross-validate the fixed model, you have already leaked the outcome into your feature set, and your cross-validated estimate is optimistic for the same reason your training estimate is. Even done correctly, cross-validation gives you an honest estimate of poor performance; it does not manufacture the events you are missing. No resampling scheme creates information that the events don’t contain.
What actually helps
Outcome-blind dimension reduction. Reduce dimensionality before you look at the outcome, using biology rather than the response. Restricting to a curated pathway, collapsing to gene-set scores, or filtering on variance are all defensible because none of them consults the outcome and so none of them spends your EPV budget. This is unsupervised triage, and it is the cheapest honest way to bring the predictor count down toward what your events can support.
Penalization. Ridge and elastic-net models don’t need EPV above ten in the naive sense because they don’t estimate each coefficient freely; shrinkage borrows strength across predictors and buys back the stability that raw dimensionality destroys. A penalized model with a well-chosen penalty is often the only thing that turns a hopeless EPV into a usable one, and in high dimensions it is the price of admission.
A sample-size calculation instead of a rule of thumb. Riley and colleagues, with Harrell among the authors, worked out how to compute the minimum sample size a prediction model actually needs: enough that the expected global shrinkage factor is at least 0.9, that the gap between apparent and optimism-adjusted R² is small, and that the overall outcome proportion is estimated precisely. Their worked examples land anywhere from about 5 to 23 events per parameter, which is their argument for retiring the fixed 10 EPV rule. Running that calculation up front tells you whether the study you are about to analyze can support the model you want, and sometimes the honest answer is that it can support a much smaller one. That is a better thing to learn before the analysis than after the failed replication.
What I do now
I compute EPV before I do anything else, using events (not patients) over candidate predictors (not final ones). If the number is small, and it usually is in omics, I do not proceed as if it were large. I cut dimensionality with unsupervised, outcome-blind steps first, I penalize hard, and I never free-estimate more parameters than the events can carry. I run the whole pipeline inside cross-validation, selection included, and I read the cross-validated number as a diagnosis rather than a cure. When I am designing a study rather than rescuing one, I run the sample-size calculation up front, because the most efficient way to fix an EPV problem is to not create it.
Resources
- Peduzzi, Concato, Kemper, Holford, Feinstein, A simulation study of the number of events per variable in logistic regression analysis, Journal of Clinical Epidemiology 1996;49(12):1373–1379.
- Riley, Snell, Ensor, Burke, Harrell, Moons, Collins, Minimum sample size for developing a multivariable prediction model: Part II, binary and time-to-event outcomes, Statistics in Medicine 2019;38(7):1276–1296.
- Frank Harrell, Regression Modeling Strategies, chapter 4. On degrees of freedom, the cost of variable selection, and penalization.
Last in this run: why a single held-out test set, the thing we treat as the gold standard of validation, is one of the weakest ways to estimate performance in the p ≫ n world, and what to do instead. Comments and pushback welcome.